Проанализированный URL
https://test.urbanpetsgrooming.in
Измерено 16 часов назад
Оценка AI-Ready
Хорошо
из 100
Экономия токенов
Разбивка оценки
Новые протоколы
Обнаружено 0 из 6Well-known эндпоинты, которые ищут ИИ-агенты. Обнаружено — значит агент может автоматически найти и подключиться к вашему сервису.
-
OAuth Protected Resource RFC 9728
/.well-known/oauth-protected-resource -
OAuth Discovery RFC 8414
/.well-known/oauth-authorization-server -
MCP Server Card SEP-1649 draft
/.well-known/mcp/server-card.json -
A2A Agent Card A2A v1.0
/.well-known/agent-card.json -
API Catalog RFC 9727
/.well-known/api-catalog -
Agent Skills index Discovery RFC v0.2.0 draft
/.well-known/agent-skills/index.json
Само это не удержится. Мониторинга пока нет — запишитесь, и мы сообщим, когда он появится.
Вы в списке! Мы уведомим вас о запуске.
Что мы измерили No Markdown for Agents support detected
Ваш сайт не поддерживает Markdown for Agents. Этот стандарт Cloudflare позволяет ИИ-агентам запрашивать контент в формате markdown, сокращая использование токенов на ~80%.
Как внедрить
Реализуйте одно или несколько: (1) Отвечать на Accept: text/markdown контентом в формате markdown. (2) Обслуживать URL с .md (например, /page.md). (3) Добавить теги <link rel="alternate" type="text/markdown">. (4) Добавить HTTP-заголовки Link для обнаружения markdown.
Что мы измерили Content ratio: 4.1% (264 content chars / 6515 HTML bytes)
На вашей странице низкое соотношение фактического контента к общему HTML. Большая часть веса страницы приходится на разметку, скрипты или стили, а не на контент.
Как внедрить
Перенесите CSS во внешние таблицы стилей, удалите inline-стили, минимизируйте JavaScript и убедитесь, что HTML сфокусирован на структуре контента.
Что мы измерили No llms.txt found
На вашем сайте нет файла llms.txt. Это формирующийся стандарт для помощи ИИ-агентам в понимании структуры вашего сайта.
Как внедрить
Создайте файл /llms.txt в соответствии со спецификацией llmstxt.org. Включите описание сайта и ссылки на ваши ключевые страницы.
Что мы измерили No Content-Signal found (robots.txt or HTTP headers)
Директивы Content-Signal не найдены. Они сообщают ИИ-агентам, как можно использовать ваш контент (поисковая индексация, ИИ-ввод, данные для обучения). Рекомендуемое расположение — robots.txt.
Как внедрить
Добавьте Content-Signal в ваш robots.txt: User-agent: *\nContent-Signal: search=yes, ai-input=yes, ai-train=no. Также можно добавить как HTTP-заголовок в markdown-ответах.

The pet lover’s field guide

## Life with pets,
*one paw at a time.*

Find your way around the world of dogs, cats and everyday pet care.

Search pet topics

[Explore dogs](https://test.urbanpetsgrooming.in/dog-breeds/) [Explore cats](https://test.urbanpetsgrooming.in/cat-breeds/)
PetsArmy | The pet care and breed guide [Skip to content](https://test.urbanpetsgrooming.in/#main) [PetsArmy](https://test.urbanpetsgrooming.in/) The pet lover’s field guide # Life with pets, *one paw at a time.* Find your way around the world of dogs, cats and everyday pet care. Search pet topics Search [Explore dogs](https://test.urbanpetsgrooming.in/dog-breeds/) [Explore cats](https://test.urbanpetsgrooming.in/cat-breeds/) 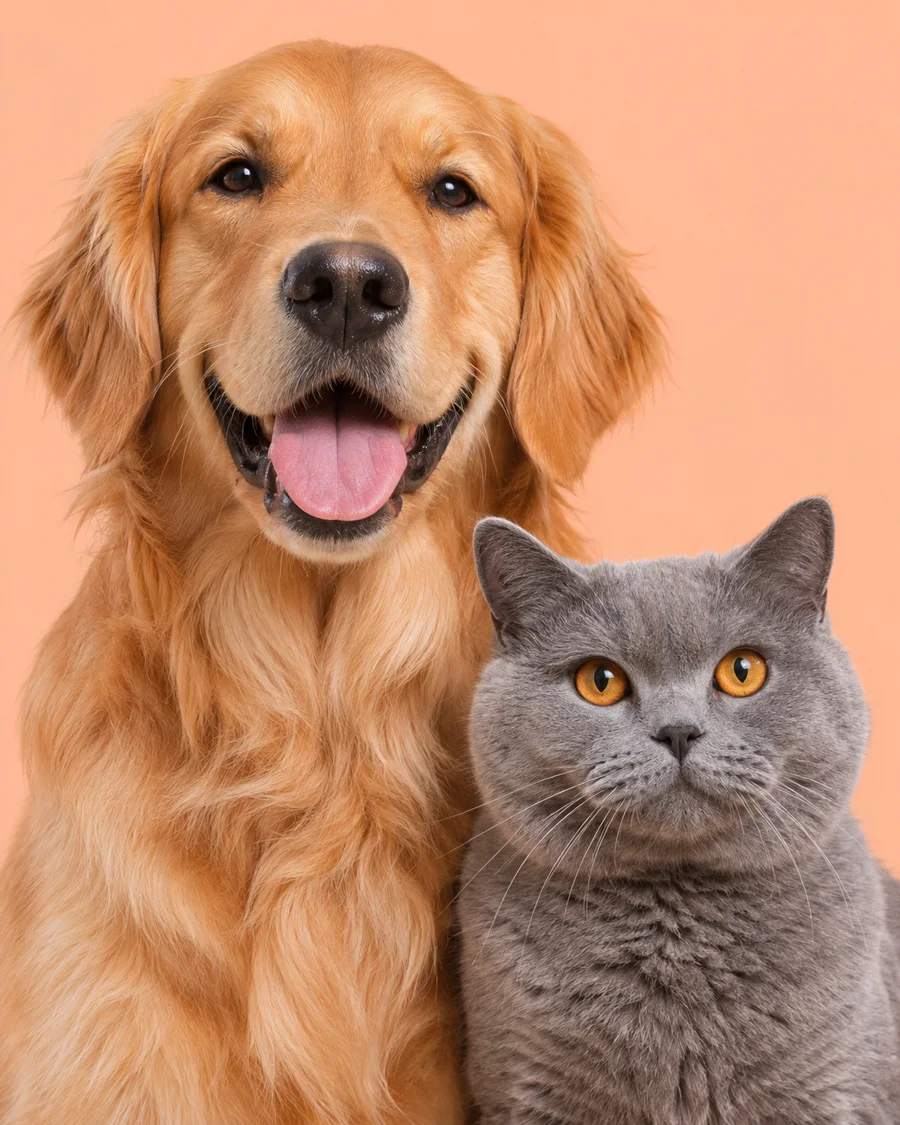 Explore PetsArmy ## What are you curious about? [Open topic directory](https://test.urbanpetsgrooming.in/explore/) [Dog breeds](https://test.urbanpetsgrooming.in/explore/#dog-breeds) [Cat breeds](https://test.urbanpetsgrooming.in/explore/#cat-breeds) [Breed comparisons](https://test.urbanpetsgrooming.in/explore/#compare) [Pet tools and calculators](https://test.urbanpetsgrooming.in/explore/#pet-tools) [Pets News](https://test.urbanpetsgrooming.in/explore/#pets-news) [Famous pets](https://test.urbanpetsgrooming.in/explore/#famous-pets) [Pet games and quizzes](https://test.urbanpetsgrooming.in/explore/#games) [Groomers and vets](https://test.urbanpetsgrooming.in/explore/#directory) [Pet care guides](https://test.urbanpetsgrooming.in/explore/#pet-care) [Pet AI tools](https://test.urbanpetsgrooming.in/explore/#pet-ai)
Загрузите этот файл как /index.md на ваш сервер, чтобы ИИ-агенты могли получить доступ к чистой версии вашей страницы. Вы также можете настроить согласование контента Accept: text/markdown для автоматической отдачи.
Сгенерированный llms.txt для этой отдельной страницы
# PetsArmy

> Discover dogs, cats and the everyday care questions that come with them.

## Main
- [PetsArmy | The pet care and breed guide](https://test.urbanpetsgrooming.in): Discover dogs, cats and the everyday care questions that come with them.
- [PetsArmy](https://test.urbanpetsgrooming.in/)
- [Dogs](https://test.urbanpetsgrooming.in/dog-breeds/)
- [Cats](https://test.urbanpetsgrooming.in/cat-breeds/)
- [Compare](https://test.urbanpetsgrooming.in/compare/)
- [Shop](https://test.urbanpetsgrooming.in/shop/)
- [Cart](https://test.urbanpetsgrooming.in/cart/)
- [Marketplace](https://test.urbanpetsgrooming.in/pet-marketplace/)
- [Tools](https://test.urbanpetsgrooming.in/explore/)

## Blog
- [Blog](https://test.urbanpetsgrooming.in/blog/)
Полный llms.txt требует анализа всего домена (скоро появится)
Загрузите этот файл по адресу https://test.urbanpetsgrooming.in/llms.txt в корень вашего домена. ИИ-агенты, такие как ChatGPT, Claude и Perplexity, проверяют этот файл для понимания структуры вашего сайта.
Доступность
Content available without JavaScript
Main content starts at 40% of HTML
Page size: 6KB
Обнаруживаемость ИИ
All major AI search bots allowed
Sitemap found
robots.txt exists
No llms.txt found
Структурированные данные
JSON-LD found: Organization
All OG tags present
Meta description: 72 chars
Canonical URL present
lang="en"
Семантический HTML
Clean heading hierarchy
Has <main>
6 semantic elements, 12 divs (ratio: 33%)
1/1 images with meaningful alt text
Avg div depth: 1.0, max: 2
Эффективность контента
96% token reduction (HTML→Markdown)
Content ratio: 4.1% (264 content chars / 6515 HTML bytes)
HTML size: 6KB
0/118 elements with inline styles (0.0%)
{
"url": "https://test.urbanpetsgrooming.in",
"timestamp": 1795314442364,
"fetch": {
"mode": "simple",
"timeMs": 441,
"htmlSizeBytes": 6515,
"supportsMarkdown": false,
"markdownAgents": {
"contentNegotiation": false,
"mdUrl": {
"found": false,
"url": null
},
"linkTag": {
"found": false,
"url": null
},
"linkHeader": {
"found": false,
"url": null
},
"responseHeaders": {
"contentSignal": null,
"xMarkdownTokens": null,
"vary": null
},
"frontmatter": {
"present": false,
"fields": [],
"level": "none"
},
"level": "none"
},
"statusCode": 200
},
"extraction": {
"title": "PetsArmy | The pet care and breed guide",
"excerpt": "Discover dogs, cats and the everyday care questions that come with them.",
"byline": null,
"siteName": "PetsArmy",
"lang": "en",
"contentLength": 264,
"metadata": {
"description": "Discover dogs, cats and the everyday care questions that come with them.",
"ogTitle": "PetsArmy | The pet care and breed guide",
"ogDescription": "Discover dogs, cats and the everyday care questions that come with them.",
"ogImage": "https://test.urbanpetsgrooming.in/assets/pets-900.webp",
"ogType": "website",
"canonical": "https://test.urbanpetsgrooming.in/",
"lang": "en",
"schemas": [
{
"@context": "https://schema.org",
"@type": "Organization",
"name": "PetsArmy",
"url": "https://test.urbanpetsgrooming.in/",
"@id": "https://test.urbanpetsgrooming.in/#organization"
}
],
"robotsMeta": null,
"author": null,
"generator": null,
"markdownAlternateHref": null
}
},
"markdown": "The pet lover’s field guide\n\n## Life with pets,\n*one paw at a time.*\n\nFind your way around the world of dogs, cats and everyday pet care.\n\nSearch pet topics\n\n[Explore dogs](https://test.urbanpetsgrooming.in/dog-breeds/) [Explore cats](https://test.urbanpetsgrooming.in/cat-breeds/)\n",
"fullPageMarkdown": "PetsArmy | The pet care and breed guide [Skip to content](https://test.urbanpetsgrooming.in/#main)\n\n[PetsArmy](https://test.urbanpetsgrooming.in/)\n\nThe pet lover’s field guide\n\n# Life with pets,\n*one paw at a time.*\n\nFind your way around the world of dogs, cats and everyday pet care.\n\nSearch pet topics Search\n\n[Explore dogs](https://test.urbanpetsgrooming.in/dog-breeds/) [Explore cats](https://test.urbanpetsgrooming.in/cat-breeds/)\n\n\n\nExplore PetsArmy\n\n## What are you curious about?\n\n[Open topic directory](https://test.urbanpetsgrooming.in/explore/)\n\n[Dog breeds](https://test.urbanpetsgrooming.in/explore/#dog-breeds) [Cat breeds](https://test.urbanpetsgrooming.in/explore/#cat-breeds) [Breed comparisons](https://test.urbanpetsgrooming.in/explore/#compare) [Pet tools and calculators](https://test.urbanpetsgrooming.in/explore/#pet-tools) [Pets News](https://test.urbanpetsgrooming.in/explore/#pets-news) [Famous pets](https://test.urbanpetsgrooming.in/explore/#famous-pets) [Pet games and quizzes](https://test.urbanpetsgrooming.in/explore/#games) [Groomers and vets](https://test.urbanpetsgrooming.in/explore/#directory) [Pet care guides](https://test.urbanpetsgrooming.in/explore/#pet-care) [Pet AI tools](https://test.urbanpetsgrooming.in/explore/#pet-ai)\n",
"markdownStats": {
"images": 0,
"links": 2,
"tables": 0,
"codeBlocks": 0,
"headings": 1
},
"tokens": {
"htmlTokens": 1680,
"markdownTokens": 75,
"reduction": 1605,
"reductionPercent": 96
},
"score": {
"score": 85,
"grade": "B",
"rubricVersion": 3,
"dimensions": {
"accessibility": {
"score": 94,
"weight": 30,
"grade": "A",
"checks": {
"content_without_js": {
"score": 100,
"weight": 55,
"evidence": "proven",
"details": "Content available without JavaScript"
},
"fast_content_position": {
"score": 75,
"weight": 25,
"evidence": "plausible",
"details": "Main content starts at 40% of HTML"
},
"reasonable_page_size": {
"score": 100,
"weight": 20,
"evidence": "plausible",
"details": "Page size: 6KB"
}
}
},
"aiDiscoverability": {
"score": 60,
"weight": 25,
"grade": "C",
"checks": {
"robots_allows_ai_bots": {
"score": 100,
"weight": 35,
"evidence": "proven",
"details": "All major AI search bots allowed"
},
"supports_markdown_negotiation": {
"score": 0,
"weight": 20,
"evidence": "plausible",
"details": "No Markdown for Agents support detected"
},
"has_sitemap": {
"score": 100,
"weight": 15,
"evidence": "plausible",
"details": "Sitemap found"
},
"has_robots_txt": {
"score": 100,
"weight": 10,
"evidence": "plausible",
"details": "robots.txt exists"
},
"has_llms_txt": {
"score": 0,
"weight": 10,
"evidence": "speculative",
"details": "No llms.txt found"
},
"has_content_signals": {
"score": 0,
"weight": 10,
"evidence": "speculative",
"details": "No Content-Signal found (robots.txt or HTTP headers)",
"mechanisms": {
"robotsTxt": false,
"httpHeader": false,
"policy": false
}
}
}
},
"structuredData": {
"score": 100,
"weight": 20,
"grade": "A",
"checks": {
"has_schema_org": {
"score": 100,
"weight": 35,
"evidence": "proven",
"details": "JSON-LD found: Organization"
},
"has_open_graph": {
"score": 100,
"weight": 20,
"evidence": "plausible",
"details": "All OG tags present"
},
"has_meta_description": {
"score": 100,
"weight": 20,
"evidence": "plausible",
"details": "Meta description: 72 chars"
},
"has_canonical_url": {
"score": 100,
"weight": 15,
"evidence": "plausible",
"details": "Canonical URL present"
},
"has_lang_attribute": {
"score": 100,
"weight": 10,
"evidence": "plausible",
"details": "lang=\"en\""
}
}
},
"semanticHtml": {
"score": 100,
"weight": 15,
"grade": "A",
"checks": {
"proper_heading_hierarchy": {
"score": 100,
"weight": 30,
"evidence": "plausible",
"details": "Clean heading hierarchy"
},
"uses_article_or_main": {
"score": 100,
"weight": 25,
"evidence": "plausible",
"details": "Has <main>"
},
"semantic_elements": {
"score": 100,
"weight": 20,
"evidence": "plausible",
"details": "6 semantic elements, 12 divs (ratio: 33%)"
},
"meaningful_alt_texts": {
"score": 100,
"weight": 15,
"evidence": "plausible",
"details": "1/1 images with meaningful alt text"
},
"low_div_nesting": {
"score": 100,
"weight": 10,
"evidence": "speculative",
"details": "Avg div depth: 1.0, max: 2"
}
}
},
"contentEfficiency": {
"score": 70,
"weight": 10,
"grade": "C",
"checks": {
"token_reduction_ratio": {
"score": 100,
"weight": 40,
"evidence": "speculative",
"details": "96% token reduction (HTML→Markdown)"
},
"content_to_noise_ratio": {
"score": 0,
"weight": 30,
"evidence": "speculative",
"details": "Content ratio: 4.1% (264 content chars / 6515 HTML bytes)"
},
"reasonable_page_weight": {
"score": 100,
"weight": 20,
"evidence": "speculative",
"details": "HTML size: 6KB"
},
"minimal_inline_styles": {
"score": 100,
"weight": 10,
"evidence": "speculative",
"details": "0/118 elements with inline styles (0.0%)"
}
}
}
}
},
"recommendations": [
{
"id": "add_markdown_negotiation",
"priority": "critical",
"category": "aiDiscoverability",
"titleKey": "rec.add_markdown_negotiation.title",
"descriptionKey": "rec.add_markdown_negotiation.description",
"howToKey": "rec.add_markdown_negotiation.howto",
"howToStepKeys": null,
"effort": "significant",
"estimatedImpact": 5,
"maxImpact": 5,
"evidence": "plausible",
"checkScore": 0,
"checkDetails": "No Markdown for Agents support detected"
},
{
"id": "improve_content_ratio",
"priority": "high",
"category": "contentEfficiency",
"titleKey": "rec.improve_content_ratio.title",
"descriptionKey": "rec.improve_content_ratio.description",
"howToKey": "rec.improve_content_ratio.howto",
"howToStepKeys": null,
"effort": "moderate",
"estimatedImpact": 3,
"maxImpact": 3,
"evidence": "speculative",
"checkScore": 0,
"checkDetails": "Content ratio: 4.1% (264 content chars / 6515 HTML bytes)"
},
{
"id": "add_llms_txt",
"priority": "high",
"category": "aiDiscoverability",
"titleKey": "rec.add_llms_txt.title",
"descriptionKey": "rec.add_llms_txt.description",
"howToKey": "rec.add_llms_txt.howto",
"howToStepKeys": null,
"effort": "quick-win",
"estimatedImpact": 2.5,
"maxImpact": 2.5,
"evidence": "speculative",
"checkScore": 0,
"checkDetails": "No llms.txt found"
},
{
"id": "add_content_signals",
"priority": "high",
"category": "aiDiscoverability",
"titleKey": "rec.add_content_signals.title",
"descriptionKey": "rec.add_content_signals.description",
"howToKey": "rec.add_content_signals.howto",
"howToStepKeys": null,
"effort": "quick-win",
"estimatedImpact": 2.5,
"maxImpact": 2.5,
"evidence": "speculative",
"checkScore": 0,
"checkDetails": "No Content-Signal found (robots.txt or HTTP headers)"
}
],
"llmsTxtPreview": "# PetsArmy\n\n> Discover dogs, cats and the everyday care questions that come with them.\n\n## Main\n- [PetsArmy | The pet care and breed guide](https://test.urbanpetsgrooming.in): Discover dogs, cats and the everyday care questions that come with them.\n- [PetsArmy](https://test.urbanpetsgrooming.in/)\n- [Dogs](https://test.urbanpetsgrooming.in/dog-breeds/)\n- [Cats](https://test.urbanpetsgrooming.in/cat-breeds/)\n- [Compare](https://test.urbanpetsgrooming.in/compare/)\n- [Shop](https://test.urbanpetsgrooming.in/shop/)\n- [Cart](https://test.urbanpetsgrooming.in/cart/)\n- [Marketplace](https://test.urbanpetsgrooming.in/pet-marketplace/)\n- [Tools](https://test.urbanpetsgrooming.in/explore/)\n\n## Blog\n- [Blog](https://test.urbanpetsgrooming.in/blog/)\n\n",
"llmsTxtExisting": null,
"emergingProtocols": {
"oauthProtectedResource": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/oauth-protected-resource"
},
"oauthDiscovery": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/oauth-authorization-server"
},
"mcpServerCard": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/mcp/server-card.json",
"draft": true
},
"a2aAgentCard": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/agent-card.json"
},
"apiCatalog": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/api-catalog"
},
"agentSkills": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/agent-skills/index.json",
"draft": true
},
"count": 0,
"total": 6
},
"botAccess": {
"probed": true,
"bot": "OAI-SearchBot",
"controlStatus": 200,
"botStatus": 200,
"discriminates": false,
"refusedAsBot": false,
"edge": null,
"verifiable": false,
"detail": "This origin answers OAI-SearchBot exactly as it answers any other client (200). No edge-level filtering of AI crawlers observed."
},
"snippets": [
{
"id": "add_llms_txt",
"title": "Create /llms.txt",
"description": "Upload this file to your web root. It tells AI agents what your site is about and which pages matter.",
"language": "markdown",
"code": "# PetsArmy\n\n> Discover dogs, cats and the everyday care questions that come with them.\n\n## Main\n- [PetsArmy | The pet care and breed guide](https://test.urbanpetsgrooming.in): Discover dogs, cats and the everyday care questions that come with them.\n- [PetsArmy](https://test.urbanpetsgrooming.in/)\n- [Dogs](https://test.urbanpetsgrooming.in/dog-breeds/)\n- [Cats](https://test.urbanpetsgrooming.in/cat-breeds/)\n- [Compare](https://test.urbanpetsgrooming.in/compare/)\n- [Shop](https://test.urbanpetsgrooming.in/shop/)\n- [Cart](https://test.urbanpetsgrooming.in/cart/)\n- [Marketplace](https://test.urbanpetsgrooming.in/pet-marketplace/)\n- [Tools](https://test.urbanpetsgrooming.in/explore/)\n\n## Blog\n- [Blog](https://test.urbanpetsgrooming.in/blog/)\n\n",
"filename": "/llms.txt"
},
{
"id": "add_content_signals",
"title": "Add Content-Signal directives",
"description": "Content-Signal tells AI agents how they may use your content. The canonical location is robots.txt, but you can also expose it as an HTTP header from any stack.",
"language": "txt",
"code": "User-agent: *\nContent-Signal: search=yes, ai-input=yes, ai-train=no",
"filename": "/robots.txt",
"stacks": [
{
"id": "robots",
"label": "robots.txt",
"language": "txt",
"filename": "/robots.txt",
"code": "User-agent: *\nContent-Signal: search=yes, ai-input=yes, ai-train=no"
},
{
"id": "nginx",
"label": "Nginx",
"language": "nginx",
"filename": "server block",
"code": "# Inside your server { } block:\nadd_header Content-Signal \"search=yes, ai-input=yes, ai-train=no\" always;"
},
{
"id": "apache",
"label": "Apache",
"language": "apache",
"filename": ".htaccess",
"code": "# In .htaccess (or VirtualHost):\nHeader set Content-Signal \"search=yes, ai-input=yes, ai-train=no\""
},
{
"id": "wordpress",
"label": "WordPress",
"language": "php",
"filename": "functions.php",
"code": "<?php\n// In your theme's functions.php or a small mu-plugin\nadd_action('send_headers', function () {\n header('Content-Signal: search=yes, ai-input=yes, ai-train=no');\n});\n\n// Optional: also append the directive to the dynamic robots.txt\nadd_filter('robots_txt', function ($output) {\n return $output . \"\\nContent-Signal: search=yes, ai-input=yes, ai-train=no\\n\";\n}, 10, 1);"
},
{
"id": "nextjs",
"label": "Next.js",
"language": "typescript",
"filename": "middleware.ts",
"code": "// middleware.ts (Next.js 13+ App Router or Pages Router)\nimport { NextResponse } from 'next/server';\nexport function middleware() {\n const res = NextResponse.next();\n res.headers.set(\n 'Content-Signal',\n 'search=yes, ai-input=yes, ai-train=no'\n );\n return res;\n}\nexport const config = { matcher: '/:path*' };"
},
{
"id": "cloudflare",
"label": "Cloudflare Workers",
"language": "javascript",
"filename": "worker.js",
"code": "// Cloudflare Worker that proxies your origin and adds the header\nexport default {\n async fetch(request, env, ctx) {\n const res = await fetch(request);\n const newRes = new Response(res.body, res);\n newRes.headers.set(\n 'Content-Signal',\n 'search=yes, ai-input=yes, ai-train=no'\n );\n return newRes;\n },\n};"
},
{
"id": "express",
"label": "Express / Fastify",
"language": "javascript",
"filename": "server.js",
"code": "// Express\napp.use((req, res, next) => {\n res.setHeader('Content-Signal', 'search=yes, ai-input=yes, ai-train=no');\n next();\n});\n\n// Fastify\nfastify.addHook('onSend', (request, reply, payload, done) => {\n reply.header('Content-Signal', 'search=yes, ai-input=yes, ai-train=no');\n done();\n});"
}
]
},
{
"id": "add_markdown_negotiation",
"title": "Support Markdown for Agents",
"description": "Let AI agents request a clean Markdown version of any page via content negotiation, .md alternate URLs, link tags or Link headers.",
"language": "html",
"code": "<!-- Mechanism 3: link tag advertising the .md alternate -->\n<link rel=\"alternate\" type=\"text/markdown\" href=\"/page.md\">",
"filename": "<head>",
"stacks": [
{
"id": "html",
"label": "HTML <head>",
"language": "html",
"filename": "<head>",
"code": "<!-- Mechanism 3: link tag advertising the .md alternate -->\n<link rel=\"alternate\" type=\"text/markdown\" href=\"/page.md\">"
},
{
"id": "express",
"label": "Express",
"language": "javascript",
"filename": "server.js",
"code": "// Mechanisms 1 + 4: content negotiation + Link header\napp.get('/page', (req, res) => {\n res.setHeader('Vary', 'Accept');\n res.setHeader('Link', '</page.md>; rel=\"alternate\"; type=\"text/markdown\"');\n if ((req.headers.accept || '').includes('text/markdown')) {\n res.type('text/markdown; charset=utf-8');\n return res.send(renderMarkdown('page'));\n }\n res.render('page');\n});"
},
{
"id": "fastify",
"label": "Fastify",
"language": "javascript",
"filename": "server.js",
"code": "// Mechanisms 1 + 4: content negotiation + Link header\nfastify.get('/page', async (req, reply) => {\n reply.header('Vary', 'Accept');\n reply.header('Link', '</page.md>; rel=\"alternate\"; type=\"text/markdown\"');\n if ((req.headers.accept || '').includes('text/markdown')) {\n return reply.type('text/markdown; charset=utf-8').send(renderMarkdown('page'));\n }\n return reply.view('/page.ejs');\n});"
},
{
"id": "nextjs",
"label": "Next.js",
"language": "typescript",
"filename": "app/page/route.ts",
"code": "// Next.js App Router — Route Handler returning Markdown\nimport { NextRequest } from 'next/server';\nimport { renderMarkdown } from '@/lib/md';\nexport async function GET(req: NextRequest) {\n const accept = req.headers.get('accept') || '';\n if (accept.includes('text/markdown')) {\n return new Response(await renderMarkdown('page'), {\n headers: {\n 'Content-Type': 'text/markdown; charset=utf-8',\n 'Vary': 'Accept',\n },\n });\n }\n // Fall through to the page component\n return new Response(null, { status: 404 });\n}"
},
{
"id": "wordpress",
"label": "WordPress",
"language": "php",
"filename": "functions.php",
"code": "<?php\n// Mechanism 1: respond to Accept: text/markdown on the same URL\nadd_action('template_redirect', function () {\n if (!is_singular()) return;\n $accept = $_SERVER['HTTP_ACCEPT'] ?? '';\n if (strpos($accept, 'text/markdown') === false) return;\n header('Content-Type: text/markdown; charset=utf-8');\n header('Vary: Accept');\n $post = get_queried_object();\n echo \"# \" . get_the_title($post) . \"\\n\\n\";\n echo wp_strip_all_tags(apply_filters('the_content', $post->post_content));\n exit;\n});"
},
{
"id": "static",
"label": "Hugo / Jekyll / Astro",
"language": "txt",
"filename": "static/page.md",
"code": "# Mechanism 2: serve .md alongside .html\n# Hugo: place page.md in /static/ — built unchanged\n# Jekyll: drop page.md in /assets/ — copied as-is\n# Astro: src/pages/page.md.ts that exports a GET returning markdown\n\n# Then advertise with mechanism 3 in <head>:\n# <link rel=\"alternate\" type=\"text/markdown\" href=\"/page.md\">"
}
]
}
]
}Используйте наш API для программного получения данных (скоро появится)
Этот JSON предназначен для внутреннего использования — в отличие от файлов Markdown и llms.txt, его не нужно загружать на ваш сайт. Сохраните его как базовый показатель для отслеживания оценки со временем, поделитесь с командой разработчиков или интегрируйте в ваш CI/CD-конвейер.
Поделитесь результатами
Или попросите ИИ помочь это исправить
Нужно второе мнение?
У Cloudflare тоже есть бесплатный сканер, и он задаёт другой вопрос. Он оценивает то, что ваш сайт публикует для вызова агентами: MCP server cards, Agent Skills, каталоги API, DNS-записи. Мы оцениваем, может ли агент добраться до вашего контента, прочитать и понять его. Сайт может быть хорош в одном и плох в другом, так что ждите двух разных чисел: это ответы на два разных вопроса, и знать стоит оба.
Проверить test.urbanpetsgrooming.in через CloudflareВстройте ваш бейдж
Добавьте этот бейдж на ваш сайт. Он обновляется автоматически при изменении вашей оценки ИИ-готовности.
<script src="https://agentready.md/badge.js" data-id="e44f111d-4d5e-4187-b90b-8685392565ab" data-domain="test.urbanpetsgrooming.in"></script>[](https://agentready.md/ru/r/test.urbanpetsgrooming.in)Скоро: Полный анализ домена
Сканируйте весь домен, генерируйте llms.txt и отслеживайте оценку ИИ-готовности со временем. Присоединяйтесь к списку ожидания.
Вы в списке! Мы уведомим вас о запуске.