URL analysée
https://test.urbanpetsgrooming.in
Mesuré il y a 16 heures
Score AI-Ready
Bon
sur 100
Économie de tokens
Détail du score
Protocoles émergents
0 sur 6 détectésEndpoints well-known recherchés par les agents IA. Détecté signifie qu’un agent peut découvrir et se connecter automatiquement à votre service.
-
OAuth Protected Resource RFC 9728
/.well-known/oauth-protected-resource -
OAuth Discovery RFC 8414
/.well-known/oauth-authorization-server -
MCP Server Card SEP-1649 draft
/.well-known/mcp/server-card.json -
A2A Agent Card A2A v1.0
/.well-known/agent-card.json -
API Catalog RFC 9727
/.well-known/api-catalog -
Agent Skills index Discovery RFC v0.2.0 draft
/.well-known/agent-skills/index.json
Cela ne reste pas en place. La surveillance n'existe pas encore : inscrivez-vous, on vous préviendra.
Vous êtes sur la liste ! Nous vous préviendrons lors du lancement.
Ce que nous avons mesuré No Markdown for Agents support detected
Votre site ne supporte pas Markdown for Agents. Ce standard Cloudflare permet aux agents IA de demander du contenu en format markdown, réduisant l'utilisation de tokens de ~80%.
Comment implémenter
Implémentez un ou plusieurs : (1) Répondre à Accept: text/markdown avec du contenu markdown. (2) Servir des URLs .md (ex : /page.md). (3) Ajouter des balises <link rel="alternate" type="text/markdown">. (4) Ajouter des en-têtes HTTP Link pour la découverte markdown.
Ce que nous avons mesuré Content ratio: 4.1% (264 content chars / 6515 HTML bytes)
Votre page a un faible ratio de contenu réel par rapport au HTML total. Une grande partie du poids de la page est du balisage, des scripts ou des styles plutôt que du contenu.
Comment implémenter
Déplacez le CSS vers des feuilles de style externes, supprimez les styles en ligne, minimisez le JavaScript et assurez-vous que le HTML se concentre sur la structure du contenu.
Ce que nous avons mesuré No llms.txt found
Votre site n’a pas de fichier llms.txt. C’est le standard émergent pour aider les AI agents à comprendre la structure de votre site.
Comment implémenter
Créez un fichier /llms.txt en suivant la spécification de llmstxt.org. Incluez une description du site et des liens vers vos pages principales.
Ce que nous avons mesuré No Content-Signal found (robots.txt or HTTP headers)
Aucune directive Content-Signal trouvée. Celles-ci indiquent aux agents IA comment ils peuvent utiliser votre contenu (indexation, entrée IA, données d'entraînement). L'emplacement recommandé est robots.txt.
Comment implémenter
Ajoutez Content-Signal à votre robots.txt : User-agent: *\nContent-Signal: search=yes, ai-input=yes, ai-train=no. Vous pouvez aussi l'ajouter comme en-tête HTTP sur les réponses markdown.

The pet lover’s field guide

## Life with pets,
*one paw at a time.*

Find your way around the world of dogs, cats and everyday pet care.

Search pet topics

[Explore dogs](https://test.urbanpetsgrooming.in/dog-breeds/) [Explore cats](https://test.urbanpetsgrooming.in/cat-breeds/)
PetsArmy | The pet care and breed guide [Skip to content](https://test.urbanpetsgrooming.in/#main) [PetsArmy](https://test.urbanpetsgrooming.in/) The pet lover’s field guide # Life with pets, *one paw at a time.* Find your way around the world of dogs, cats and everyday pet care. Search pet topics Search [Explore dogs](https://test.urbanpetsgrooming.in/dog-breeds/) [Explore cats](https://test.urbanpetsgrooming.in/cat-breeds/) 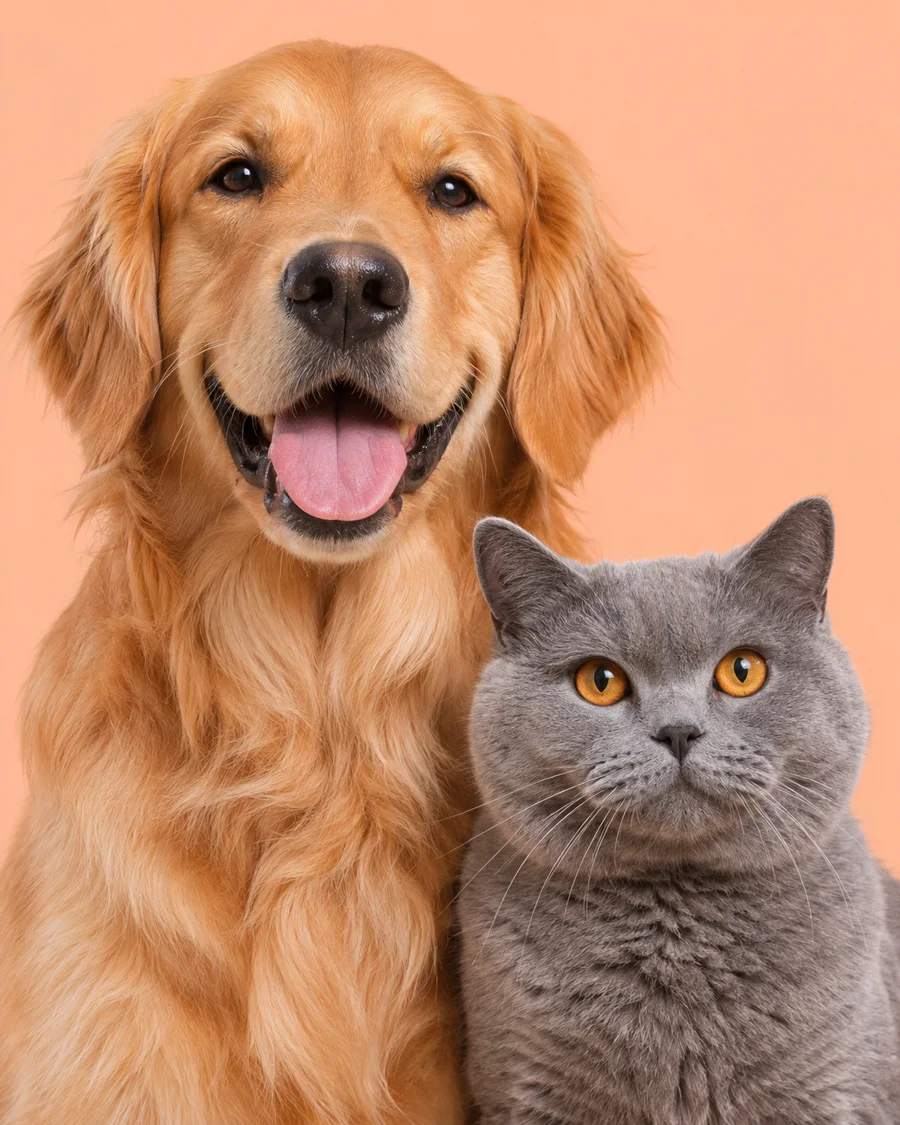 Explore PetsArmy ## What are you curious about? [Open topic directory](https://test.urbanpetsgrooming.in/explore/) [Dog breeds](https://test.urbanpetsgrooming.in/explore/#dog-breeds) [Cat breeds](https://test.urbanpetsgrooming.in/explore/#cat-breeds) [Breed comparisons](https://test.urbanpetsgrooming.in/explore/#compare) [Pet tools and calculators](https://test.urbanpetsgrooming.in/explore/#pet-tools) [Pets News](https://test.urbanpetsgrooming.in/explore/#pets-news) [Famous pets](https://test.urbanpetsgrooming.in/explore/#famous-pets) [Pet games and quizzes](https://test.urbanpetsgrooming.in/explore/#games) [Groomers and vets](https://test.urbanpetsgrooming.in/explore/#directory) [Pet care guides](https://test.urbanpetsgrooming.in/explore/#pet-care) [Pet AI tools](https://test.urbanpetsgrooming.in/explore/#pet-ai)
Téléversez ce fichier sous /index.md sur votre serveur pour que les AI agents puissent accéder à une version propre de votre page. Vous pouvez également configurer la négociation de contenu Accept: text/markdown pour le servir automatiquement.
llms.txt généré pour cette page individuelle
# PetsArmy

> Discover dogs, cats and the everyday care questions that come with them.

## Main
- [PetsArmy | The pet care and breed guide](https://test.urbanpetsgrooming.in): Discover dogs, cats and the everyday care questions that come with them.
- [PetsArmy](https://test.urbanpetsgrooming.in/)
- [Dogs](https://test.urbanpetsgrooming.in/dog-breeds/)
- [Cats](https://test.urbanpetsgrooming.in/cat-breeds/)
- [Compare](https://test.urbanpetsgrooming.in/compare/)
- [Shop](https://test.urbanpetsgrooming.in/shop/)
- [Cart](https://test.urbanpetsgrooming.in/cart/)
- [Marketplace](https://test.urbanpetsgrooming.in/pet-marketplace/)
- [Tools](https://test.urbanpetsgrooming.in/explore/)

## Blog
- [Blog](https://test.urbanpetsgrooming.in/blog/)
Le llms.txt complet nécessite une analyse de tout le domaine (bientôt disponible)
Téléversez ce fichier vers https://test.urbanpetsgrooming.in/llms.txt à la racine de votre domaine. Les AI agents comme ChatGPT, Claude et Perplexity consultent ce fichier pour comprendre la structure de votre site.
Accessibilité
Content available without JavaScript
Main content starts at 40% of HTML
Page size: 6KB
Visibilité IA
All major AI search bots allowed
Sitemap found
robots.txt exists
No llms.txt found
Données structurées
JSON-LD found: Organization
All OG tags present
Meta description: 72 chars
Canonical URL present
lang="en"
HTML sémantique
Clean heading hierarchy
Has <main>
6 semantic elements, 12 divs (ratio: 33%)
1/1 images with meaningful alt text
Avg div depth: 1.0, max: 2
Efficacité du contenu
96% token reduction (HTML→Markdown)
Content ratio: 4.1% (264 content chars / 6515 HTML bytes)
HTML size: 6KB
0/118 elements with inline styles (0.0%)
{
"url": "https://test.urbanpetsgrooming.in",
"timestamp": 1795314442364,
"fetch": {
"mode": "simple",
"timeMs": 441,
"htmlSizeBytes": 6515,
"supportsMarkdown": false,
"markdownAgents": {
"contentNegotiation": false,
"mdUrl": {
"found": false,
"url": null
},
"linkTag": {
"found": false,
"url": null
},
"linkHeader": {
"found": false,
"url": null
},
"responseHeaders": {
"contentSignal": null,
"xMarkdownTokens": null,
"vary": null
},
"frontmatter": {
"present": false,
"fields": [],
"level": "none"
},
"level": "none"
},
"statusCode": 200
},
"extraction": {
"title": "PetsArmy | The pet care and breed guide",
"excerpt": "Discover dogs, cats and the everyday care questions that come with them.",
"byline": null,
"siteName": "PetsArmy",
"lang": "en",
"contentLength": 264,
"metadata": {
"description": "Discover dogs, cats and the everyday care questions that come with them.",
"ogTitle": "PetsArmy | The pet care and breed guide",
"ogDescription": "Discover dogs, cats and the everyday care questions that come with them.",
"ogImage": "https://test.urbanpetsgrooming.in/assets/pets-900.webp",
"ogType": "website",
"canonical": "https://test.urbanpetsgrooming.in/",
"lang": "en",
"schemas": [
{
"@context": "https://schema.org",
"@type": "Organization",
"name": "PetsArmy",
"url": "https://test.urbanpetsgrooming.in/",
"@id": "https://test.urbanpetsgrooming.in/#organization"
}
],
"robotsMeta": null,
"author": null,
"generator": null,
"markdownAlternateHref": null
}
},
"markdown": "The pet lover’s field guide\n\n## Life with pets,\n*one paw at a time.*\n\nFind your way around the world of dogs, cats and everyday pet care.\n\nSearch pet topics\n\n[Explore dogs](https://test.urbanpetsgrooming.in/dog-breeds/) [Explore cats](https://test.urbanpetsgrooming.in/cat-breeds/)\n",
"fullPageMarkdown": "PetsArmy | The pet care and breed guide [Skip to content](https://test.urbanpetsgrooming.in/#main)\n\n[PetsArmy](https://test.urbanpetsgrooming.in/)\n\nThe pet lover’s field guide\n\n# Life with pets,\n*one paw at a time.*\n\nFind your way around the world of dogs, cats and everyday pet care.\n\nSearch pet topics Search\n\n[Explore dogs](https://test.urbanpetsgrooming.in/dog-breeds/) [Explore cats](https://test.urbanpetsgrooming.in/cat-breeds/)\n\n\n\nExplore PetsArmy\n\n## What are you curious about?\n\n[Open topic directory](https://test.urbanpetsgrooming.in/explore/)\n\n[Dog breeds](https://test.urbanpetsgrooming.in/explore/#dog-breeds) [Cat breeds](https://test.urbanpetsgrooming.in/explore/#cat-breeds) [Breed comparisons](https://test.urbanpetsgrooming.in/explore/#compare) [Pet tools and calculators](https://test.urbanpetsgrooming.in/explore/#pet-tools) [Pets News](https://test.urbanpetsgrooming.in/explore/#pets-news) [Famous pets](https://test.urbanpetsgrooming.in/explore/#famous-pets) [Pet games and quizzes](https://test.urbanpetsgrooming.in/explore/#games) [Groomers and vets](https://test.urbanpetsgrooming.in/explore/#directory) [Pet care guides](https://test.urbanpetsgrooming.in/explore/#pet-care) [Pet AI tools](https://test.urbanpetsgrooming.in/explore/#pet-ai)\n",
"markdownStats": {
"images": 0,
"links": 2,
"tables": 0,
"codeBlocks": 0,
"headings": 1
},
"tokens": {
"htmlTokens": 1680,
"markdownTokens": 75,
"reduction": 1605,
"reductionPercent": 96
},
"score": {
"score": 85,
"grade": "B",
"rubricVersion": 3,
"dimensions": {
"accessibility": {
"score": 94,
"weight": 30,
"grade": "A",
"checks": {
"content_without_js": {
"score": 100,
"weight": 55,
"evidence": "proven",
"details": "Content available without JavaScript"
},
"fast_content_position": {
"score": 75,
"weight": 25,
"evidence": "plausible",
"details": "Main content starts at 40% of HTML"
},
"reasonable_page_size": {
"score": 100,
"weight": 20,
"evidence": "plausible",
"details": "Page size: 6KB"
}
}
},
"aiDiscoverability": {
"score": 60,
"weight": 25,
"grade": "C",
"checks": {
"robots_allows_ai_bots": {
"score": 100,
"weight": 35,
"evidence": "proven",
"details": "All major AI search bots allowed"
},
"supports_markdown_negotiation": {
"score": 0,
"weight": 20,
"evidence": "plausible",
"details": "No Markdown for Agents support detected"
},
"has_sitemap": {
"score": 100,
"weight": 15,
"evidence": "plausible",
"details": "Sitemap found"
},
"has_robots_txt": {
"score": 100,
"weight": 10,
"evidence": "plausible",
"details": "robots.txt exists"
},
"has_llms_txt": {
"score": 0,
"weight": 10,
"evidence": "speculative",
"details": "No llms.txt found"
},
"has_content_signals": {
"score": 0,
"weight": 10,
"evidence": "speculative",
"details": "No Content-Signal found (robots.txt or HTTP headers)",
"mechanisms": {
"robotsTxt": false,
"httpHeader": false,
"policy": false
}
}
}
},
"structuredData": {
"score": 100,
"weight": 20,
"grade": "A",
"checks": {
"has_schema_org": {
"score": 100,
"weight": 35,
"evidence": "proven",
"details": "JSON-LD found: Organization"
},
"has_open_graph": {
"score": 100,
"weight": 20,
"evidence": "plausible",
"details": "All OG tags present"
},
"has_meta_description": {
"score": 100,
"weight": 20,
"evidence": "plausible",
"details": "Meta description: 72 chars"
},
"has_canonical_url": {
"score": 100,
"weight": 15,
"evidence": "plausible",
"details": "Canonical URL present"
},
"has_lang_attribute": {
"score": 100,
"weight": 10,
"evidence": "plausible",
"details": "lang=\"en\""
}
}
},
"semanticHtml": {
"score": 100,
"weight": 15,
"grade": "A",
"checks": {
"proper_heading_hierarchy": {
"score": 100,
"weight": 30,
"evidence": "plausible",
"details": "Clean heading hierarchy"
},
"uses_article_or_main": {
"score": 100,
"weight": 25,
"evidence": "plausible",
"details": "Has <main>"
},
"semantic_elements": {
"score": 100,
"weight": 20,
"evidence": "plausible",
"details": "6 semantic elements, 12 divs (ratio: 33%)"
},
"meaningful_alt_texts": {
"score": 100,
"weight": 15,
"evidence": "plausible",
"details": "1/1 images with meaningful alt text"
},
"low_div_nesting": {
"score": 100,
"weight": 10,
"evidence": "speculative",
"details": "Avg div depth: 1.0, max: 2"
}
}
},
"contentEfficiency": {
"score": 70,
"weight": 10,
"grade": "C",
"checks": {
"token_reduction_ratio": {
"score": 100,
"weight": 40,
"evidence": "speculative",
"details": "96% token reduction (HTML→Markdown)"
},
"content_to_noise_ratio": {
"score": 0,
"weight": 30,
"evidence": "speculative",
"details": "Content ratio: 4.1% (264 content chars / 6515 HTML bytes)"
},
"reasonable_page_weight": {
"score": 100,
"weight": 20,
"evidence": "speculative",
"details": "HTML size: 6KB"
},
"minimal_inline_styles": {
"score": 100,
"weight": 10,
"evidence": "speculative",
"details": "0/118 elements with inline styles (0.0%)"
}
}
}
}
},
"recommendations": [
{
"id": "add_markdown_negotiation",
"priority": "critical",
"category": "aiDiscoverability",
"titleKey": "rec.add_markdown_negotiation.title",
"descriptionKey": "rec.add_markdown_negotiation.description",
"howToKey": "rec.add_markdown_negotiation.howto",
"howToStepKeys": null,
"effort": "significant",
"estimatedImpact": 5,
"maxImpact": 5,
"evidence": "plausible",
"checkScore": 0,
"checkDetails": "No Markdown for Agents support detected"
},
{
"id": "improve_content_ratio",
"priority": "high",
"category": "contentEfficiency",
"titleKey": "rec.improve_content_ratio.title",
"descriptionKey": "rec.improve_content_ratio.description",
"howToKey": "rec.improve_content_ratio.howto",
"howToStepKeys": null,
"effort": "moderate",
"estimatedImpact": 3,
"maxImpact": 3,
"evidence": "speculative",
"checkScore": 0,
"checkDetails": "Content ratio: 4.1% (264 content chars / 6515 HTML bytes)"
},
{
"id": "add_llms_txt",
"priority": "high",
"category": "aiDiscoverability",
"titleKey": "rec.add_llms_txt.title",
"descriptionKey": "rec.add_llms_txt.description",
"howToKey": "rec.add_llms_txt.howto",
"howToStepKeys": null,
"effort": "quick-win",
"estimatedImpact": 2.5,
"maxImpact": 2.5,
"evidence": "speculative",
"checkScore": 0,
"checkDetails": "No llms.txt found"
},
{
"id": "add_content_signals",
"priority": "high",
"category": "aiDiscoverability",
"titleKey": "rec.add_content_signals.title",
"descriptionKey": "rec.add_content_signals.description",
"howToKey": "rec.add_content_signals.howto",
"howToStepKeys": null,
"effort": "quick-win",
"estimatedImpact": 2.5,
"maxImpact": 2.5,
"evidence": "speculative",
"checkScore": 0,
"checkDetails": "No Content-Signal found (robots.txt or HTTP headers)"
}
],
"llmsTxtPreview": "# PetsArmy\n\n> Discover dogs, cats and the everyday care questions that come with them.\n\n## Main\n- [PetsArmy | The pet care and breed guide](https://test.urbanpetsgrooming.in): Discover dogs, cats and the everyday care questions that come with them.\n- [PetsArmy](https://test.urbanpetsgrooming.in/)\n- [Dogs](https://test.urbanpetsgrooming.in/dog-breeds/)\n- [Cats](https://test.urbanpetsgrooming.in/cat-breeds/)\n- [Compare](https://test.urbanpetsgrooming.in/compare/)\n- [Shop](https://test.urbanpetsgrooming.in/shop/)\n- [Cart](https://test.urbanpetsgrooming.in/cart/)\n- [Marketplace](https://test.urbanpetsgrooming.in/pet-marketplace/)\n- [Tools](https://test.urbanpetsgrooming.in/explore/)\n\n## Blog\n- [Blog](https://test.urbanpetsgrooming.in/blog/)\n\n",
"llmsTxtExisting": null,
"emergingProtocols": {
"oauthProtectedResource": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/oauth-protected-resource"
},
"oauthDiscovery": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/oauth-authorization-server"
},
"mcpServerCard": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/mcp/server-card.json",
"draft": true
},
"a2aAgentCard": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/agent-card.json"
},
"apiCatalog": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/api-catalog"
},
"agentSkills": {
"exists": false,
"url": "https://test.urbanpetsgrooming.in/.well-known/agent-skills/index.json",
"draft": true
},
"count": 0,
"total": 6
},
"botAccess": {
"probed": true,
"bot": "OAI-SearchBot",
"controlStatus": 200,
"botStatus": 200,
"discriminates": false,
"refusedAsBot": false,
"edge": null,
"verifiable": false,
"detail": "This origin answers OAI-SearchBot exactly as it answers any other client (200). No edge-level filtering of AI crawlers observed."
},
"snippets": [
{
"id": "add_llms_txt",
"title": "Create /llms.txt",
"description": "Upload this file to your web root. It tells AI agents what your site is about and which pages matter.",
"language": "markdown",
"code": "# PetsArmy\n\n> Discover dogs, cats and the everyday care questions that come with them.\n\n## Main\n- [PetsArmy | The pet care and breed guide](https://test.urbanpetsgrooming.in): Discover dogs, cats and the everyday care questions that come with them.\n- [PetsArmy](https://test.urbanpetsgrooming.in/)\n- [Dogs](https://test.urbanpetsgrooming.in/dog-breeds/)\n- [Cats](https://test.urbanpetsgrooming.in/cat-breeds/)\n- [Compare](https://test.urbanpetsgrooming.in/compare/)\n- [Shop](https://test.urbanpetsgrooming.in/shop/)\n- [Cart](https://test.urbanpetsgrooming.in/cart/)\n- [Marketplace](https://test.urbanpetsgrooming.in/pet-marketplace/)\n- [Tools](https://test.urbanpetsgrooming.in/explore/)\n\n## Blog\n- [Blog](https://test.urbanpetsgrooming.in/blog/)\n\n",
"filename": "/llms.txt"
},
{
"id": "add_content_signals",
"title": "Add Content-Signal directives",
"description": "Content-Signal tells AI agents how they may use your content. The canonical location is robots.txt, but you can also expose it as an HTTP header from any stack.",
"language": "txt",
"code": "User-agent: *\nContent-Signal: search=yes, ai-input=yes, ai-train=no",
"filename": "/robots.txt",
"stacks": [
{
"id": "robots",
"label": "robots.txt",
"language": "txt",
"filename": "/robots.txt",
"code": "User-agent: *\nContent-Signal: search=yes, ai-input=yes, ai-train=no"
},
{
"id": "nginx",
"label": "Nginx",
"language": "nginx",
"filename": "server block",
"code": "# Inside your server { } block:\nadd_header Content-Signal \"search=yes, ai-input=yes, ai-train=no\" always;"
},
{
"id": "apache",
"label": "Apache",
"language": "apache",
"filename": ".htaccess",
"code": "# In .htaccess (or VirtualHost):\nHeader set Content-Signal \"search=yes, ai-input=yes, ai-train=no\""
},
{
"id": "wordpress",
"label": "WordPress",
"language": "php",
"filename": "functions.php",
"code": "<?php\n// In your theme's functions.php or a small mu-plugin\nadd_action('send_headers', function () {\n header('Content-Signal: search=yes, ai-input=yes, ai-train=no');\n});\n\n// Optional: also append the directive to the dynamic robots.txt\nadd_filter('robots_txt', function ($output) {\n return $output . \"\\nContent-Signal: search=yes, ai-input=yes, ai-train=no\\n\";\n}, 10, 1);"
},
{
"id": "nextjs",
"label": "Next.js",
"language": "typescript",
"filename": "middleware.ts",
"code": "// middleware.ts (Next.js 13+ App Router or Pages Router)\nimport { NextResponse } from 'next/server';\nexport function middleware() {\n const res = NextResponse.next();\n res.headers.set(\n 'Content-Signal',\n 'search=yes, ai-input=yes, ai-train=no'\n );\n return res;\n}\nexport const config = { matcher: '/:path*' };"
},
{
"id": "cloudflare",
"label": "Cloudflare Workers",
"language": "javascript",
"filename": "worker.js",
"code": "// Cloudflare Worker that proxies your origin and adds the header\nexport default {\n async fetch(request, env, ctx) {\n const res = await fetch(request);\n const newRes = new Response(res.body, res);\n newRes.headers.set(\n 'Content-Signal',\n 'search=yes, ai-input=yes, ai-train=no'\n );\n return newRes;\n },\n};"
},
{
"id": "express",
"label": "Express / Fastify",
"language": "javascript",
"filename": "server.js",
"code": "// Express\napp.use((req, res, next) => {\n res.setHeader('Content-Signal', 'search=yes, ai-input=yes, ai-train=no');\n next();\n});\n\n// Fastify\nfastify.addHook('onSend', (request, reply, payload, done) => {\n reply.header('Content-Signal', 'search=yes, ai-input=yes, ai-train=no');\n done();\n});"
}
]
},
{
"id": "add_markdown_negotiation",
"title": "Support Markdown for Agents",
"description": "Let AI agents request a clean Markdown version of any page via content negotiation, .md alternate URLs, link tags or Link headers.",
"language": "html",
"code": "<!-- Mechanism 3: link tag advertising the .md alternate -->\n<link rel=\"alternate\" type=\"text/markdown\" href=\"/page.md\">",
"filename": "<head>",
"stacks": [
{
"id": "html",
"label": "HTML <head>",
"language": "html",
"filename": "<head>",
"code": "<!-- Mechanism 3: link tag advertising the .md alternate -->\n<link rel=\"alternate\" type=\"text/markdown\" href=\"/page.md\">"
},
{
"id": "express",
"label": "Express",
"language": "javascript",
"filename": "server.js",
"code": "// Mechanisms 1 + 4: content negotiation + Link header\napp.get('/page', (req, res) => {\n res.setHeader('Vary', 'Accept');\n res.setHeader('Link', '</page.md>; rel=\"alternate\"; type=\"text/markdown\"');\n if ((req.headers.accept || '').includes('text/markdown')) {\n res.type('text/markdown; charset=utf-8');\n return res.send(renderMarkdown('page'));\n }\n res.render('page');\n});"
},
{
"id": "fastify",
"label": "Fastify",
"language": "javascript",
"filename": "server.js",
"code": "// Mechanisms 1 + 4: content negotiation + Link header\nfastify.get('/page', async (req, reply) => {\n reply.header('Vary', 'Accept');\n reply.header('Link', '</page.md>; rel=\"alternate\"; type=\"text/markdown\"');\n if ((req.headers.accept || '').includes('text/markdown')) {\n return reply.type('text/markdown; charset=utf-8').send(renderMarkdown('page'));\n }\n return reply.view('/page.ejs');\n});"
},
{
"id": "nextjs",
"label": "Next.js",
"language": "typescript",
"filename": "app/page/route.ts",
"code": "// Next.js App Router — Route Handler returning Markdown\nimport { NextRequest } from 'next/server';\nimport { renderMarkdown } from '@/lib/md';\nexport async function GET(req: NextRequest) {\n const accept = req.headers.get('accept') || '';\n if (accept.includes('text/markdown')) {\n return new Response(await renderMarkdown('page'), {\n headers: {\n 'Content-Type': 'text/markdown; charset=utf-8',\n 'Vary': 'Accept',\n },\n });\n }\n // Fall through to the page component\n return new Response(null, { status: 404 });\n}"
},
{
"id": "wordpress",
"label": "WordPress",
"language": "php",
"filename": "functions.php",
"code": "<?php\n// Mechanism 1: respond to Accept: text/markdown on the same URL\nadd_action('template_redirect', function () {\n if (!is_singular()) return;\n $accept = $_SERVER['HTTP_ACCEPT'] ?? '';\n if (strpos($accept, 'text/markdown') === false) return;\n header('Content-Type: text/markdown; charset=utf-8');\n header('Vary: Accept');\n $post = get_queried_object();\n echo \"# \" . get_the_title($post) . \"\\n\\n\";\n echo wp_strip_all_tags(apply_filters('the_content', $post->post_content));\n exit;\n});"
},
{
"id": "static",
"label": "Hugo / Jekyll / Astro",
"language": "txt",
"filename": "static/page.md",
"code": "# Mechanism 2: serve .md alongside .html\n# Hugo: place page.md in /static/ — built unchanged\n# Jekyll: drop page.md in /assets/ — copied as-is\n# Astro: src/pages/page.md.ts that exports a GET returning markdown\n\n# Then advertise with mechanism 3 in <head>:\n# <link rel=\"alternate\" type=\"text/markdown\" href=\"/page.md\">"
}
]
}
]
}Utilisez notre API pour obtenir ceci de manière programmatique (bientôt disponible)
Ce JSON est à usage interne — contrairement au Markdown et au llms.txt, il n’est pas destiné à être téléversé sur votre site. Conservez-le comme référence pour suivre l’évolution de votre score, partagez-le avec votre équipe de développement ou intégrez-le dans votre pipeline CI/CD.
Partagez vos résultats
Ou demandez à une IA de vous aider à l'améliorer
Envie d'un deuxième avis ?
Cloudflare propose aussi un scanner gratuit, et il pose une question différente. Il note ce que votre site publie pour que les agents l'appellent : MCP server cards, Agent Skills, catalogues d'API, enregistrements DNS. Nous notons si un agent peut atteindre votre contenu, le lire et le comprendre. Un site peut réussir l'un et échouer l'autre : attendez-vous à deux chiffres différents, ce sont les réponses à deux questions différentes, et les deux méritent d'être connues.
Analyser test.urbanpetsgrooming.in avec CloudflareIntégrez votre badge
Ajoutez ce badge à votre site. Il se met à jour automatiquement lorsque votre score de préparation à l’IA change.
<script src="https://agentready.md/badge.js" data-id="e44f111d-4d5e-4187-b90b-8685392565ab" data-domain="test.urbanpetsgrooming.in"></script>[](https://agentready.md/fr/r/test.urbanpetsgrooming.in)Bientôt : Analyse de domaine complet
Explorez l’ensemble de votre domaine, générez un llms.txt et surveillez votre score de préparation IA dans le temps. Rejoignez la liste d’attente pour être informé.
Vous êtes sur la liste ! Nous vous préviendrons lors du lancement.